The Great Migration: What I Learned Moving From Monolith to Microservices (And Back Again)

The Siren Song of Microservices

Three years ago, I was that engineer who rolled my eyes every time someone mentioned microservices at our weekly architecture reviews. Our monolith was working just fine, thank you very much. Sure, deployments took forty-five minutes and occasionally someone would push a change that brought down the entire platform, but we knew every corner of that codebase like the back of our debugging-scarred hands.
The Great Migration: What I Learned Moving From Monolith to Microservices (And Back Again)

Then Netflix happened. Not the company itself, but our collective obsession with copying their architecture. Upper management attended a conference, heard about Conway’s Law and independent deployment pipelines, and suddenly our perfectly functional e-commerce platform needed to be “cloud-native” and “resilient.” The mandate came down: break apart the monolith. I spent the next eighteen months learning why distributed systems are called the hardest problems in computer science.

What followed was a master class in unintended consequences. We started with what seemed like obvious boundaries: user service, product catalog, inventory management, order processing. Clean separation of concerns, independent deployment cycles, technology diversity. On paper, it looked elegant. In production, it looked like a game of whack-a-mole played with network timeouts and cascading failures.
Illustration for The Great Migration: What I Learned Moving From Monolith to Microservices (And Back Again)

Reality Bites: The Hidden Costs Nobody Talks About

The first thing that hits you isn’t the complexity everyone warns about. It’s the operational overhead that creeps up like water damage in your basement. Suddenly, instead of monitoring one application, we had twelve services each with their own logs, metrics, and failure modes. Our on-call rotation went from “check the database connection” to “figure out which of these twelve health checks is lying and why the payment service can’t talk to inventory.”

Distributed tracing became our religion. We implemented OpenTelemetry with the enthusiasm of new converts, tracking every HTTP call, database query, and message queue interaction. The irony wasn’t lost on me that we spent more time building observability into our twelve-service architecture than we ever spent debugging our original monolith. But when things worked, they really worked. We could deploy the recommendation engine without touching checkout, scale the product catalog independently during Black Friday traffic spikes, and let different teams choose their own technology stacks.

The real education came during our first major outage six months into the migration. What started as a simple database connection pool exhaustion in the user service spread through six other services before we figured out what was happening. In the old monolith, this would have been a five-minute fix. In our brave new microservices world, it took four engineers and two hours to trace through service meshes, circuit breakers, and retry policies. We learned that distributed systems don’t fail gracefully by default. They fail creatively.

The Pendulum Swings: When Microservices Work (And When They Don’t)

Here’s what three years of production microservices taught me: the architecture isn’t inherently good or bad, but it’s definitely not neutral. Microservices work well when you have clear domain boundaries, teams that can own services end-to-end, and the operational maturity to handle distributed systems complexity. They’re terrible when you’re still figuring out your product-market fit, when your team has five developers, or when your “microservice” is just a REST API wrapper around database tables.

We hit our stride around month fourteen. Our checkout flow, which originally lived in the monolith as a single transaction, became an orchestrated dance between payment processing, inventory reservation, and order fulfillment services. Each service could scale independently, fail independently, and be deployed independently. During our biggest traffic day ever, we scaled the payment service to handle 10x normal load while keeping everything else at baseline. Try doing that with a monolith.

But the sweet spot was narrower than I expected. Services that were too small became chatty and hard to reason about. Services that were too large defeated the purpose of the architecture. We spent months refactoring boundaries, merging services that shouldn’t have been split, and splitting services that had grown too large. The “right” size turned out to be less about lines of code and more about team ownership and deployment frequency.

The Plot Twist: Going Back to the Monolith (Sort Of)

Last year, we made a decision that surprised everyone, including myself. We consolidated six of our smaller services back into what we now call a “modular monolith.” Not because microservices failed, but because we learned that distributed systems complexity should be earned, not inherited by default. Some parts of our domain genuinely benefited from service boundaries. Others just added latency and operational overhead without meaningful benefits.

The modular monolith approach kept the benefits we cared about: clear module boundaries, independent testing, and the ability to extract services when we actually needed to scale or deploy independently. But it eliminated the network hops, the distributed transaction complexity, and the operational overhead of managing services that didn’t need to be services. We kept the payment and inventory services separate because they have different scaling profiles and compliance requirements. But user preferences and notification settings? Those went back into the main application as clearly defined modules.

What I discovered is that the real value wasn’t in the architectural pattern itself, but in the discipline it forced us to adopt. Writing services with clean APIs made us better at writing modules with clean interfaces. Thinking about failure modes in distributed systems made us better at defensive programming everywhere. The microservices migration wasn’t a destination, it was an education.

The Real Trade-offs Nobody Puts in the Conference Slides

After living through both sides of this architectural divide, the trade-offs are clearer than they were from the outside. Microservices buy you organizational scalability at the cost of system complexity. They enable independent deployment and technology diversity at the cost of distributed systems operational overhead. They provide fault isolation at the cost of distributed transaction complexity. None of these trade-offs are inherently good or bad, but they’re real and they have consequences that compound over time.

The monolith gives you consistency, simplicity, and easy debugging at the cost of deployment coordination and technology lock-in. You can reason about the entire system in your head, but you can’t deploy a hotfix to one component without potentially affecting everything else. Choose your constraints wisely.

What’s your experience been with this architectural pendulum? I’m curious whether other teams have found similar sweet spots or whether the trade-offs look different in other domains. The comments are open, and I promise not to judge you if you’re still running a monolith in 2024.
Your First Production API: The Patterns That Actually Matter

Why Your Second API Will Be Better Than Your First

Every senior engineer has that one API buried deep in production that makes them wince. Mine was a user management service that somehow required seventeen different endpoints just to update a profile picture. The authentication was held together with duct tape and hope, and the error messages were about as helpful as a chocolate teapot. But here’s the thing: building terrible APIs is part of the learning process, and recognizing what makes them terrible is the first step toward building something elegant.

Your First Production API: The Patterns That Actually Matter

The good news is that API design follows predictable patterns. Once you understand these patterns, you can sidestep most of the common pitfalls that turn promising services into maintenance nightmares. The patterns we’ll cover aren’t theoretical computer science concepts. They’re practical solutions to problems you’ll encounter the moment real users start hitting your endpoints.

Start with the assumption that your API will outlive your current job, your current framework, and possibly your current sanity. Design accordingly.

REST: Your Training Wheels for Thinking About Resources

REST gets a lot of grief these days, mostly from people who’ve never had to explain to a junior developer why their endpoint is called `GET /users/delete/42`. REST isn’t perfect, but it gives you a mental framework for thinking about your API as a collection of resources rather than a grab bag of remote procedure calls.

The core insight of REST is embarrassingly simple: map your business entities to URLs and use HTTP verbs to describe actions. Users become `/users`, orders become `/orders`, and so on. Need to create a user? `POST /users`. Need to fetch a specific user? `GET /users/42`. Need to update that user? `PUT /users/42`. This predictability is a gift to both you and your API consumers.

Here’s where most people go wrong: they try to force every operation into this resource model. Sometimes you genuinely need to trigger an action that doesn’t map cleanly to CRUD operations. A password reset isn’t really updating a user, it’s starting a process. In these cases, create a resource for the action itself. `POST /password-resets` is clearer than `POST /users/reset-password` and doesn’t contort your mental model.

The real value of REST isn’t in the theological purity of your URLs. It’s in the consistency that emerges when you think systematically about how clients interact with your data. Your future self, debugging at 2 AM, will thank you for this consistency.

Error Handling: The Art of Failing Gracefully

Nothing reveals an API’s maturity like its error responses. Amateur APIs return generic 500 errors with stack traces. Professional APIs return structured error objects that help clients recover gracefully. The difference between the two often determines whether developers will integrate with your service or quietly find an alternative.

Start with HTTP status codes, but don’t stop there. A 400 response tells the client something went wrong with their request, but it doesn’t tell them what or how to fix it. Your error responses should include machine-readable error codes and human-readable messages. Think about this structure: a top-level error code that clients can switch on, a descriptive message for debugging, and when applicable, field-specific validation errors that point to exactly what went wrong.

Consistency matters more than perfection here. Pick an error format and stick with it across your entire API. Whether you choose RFC 7807’s Problem Details format or roll your own, the key is predictability. Clients should be able to write error handling code once and reuse it across all your endpoints.

One pattern that’s saved me countless support tickets: include a trace ID in every error response. When something goes wrong in production, you want to be able to grep your logs and find the exact request that caused the problem. Your error response becomes a breadcrumb trail leading back to the root cause.

Authentication and Rate Limiting: Protecting Your Sanity

Authentication is not optional, even for internal APIs. That “temporary” service you built for the mobile team will eventually be discovered by other teams, then by partners, then by that one enthusiastic intern who decides to stress test it with a million requests. Plan for this inevitability.

API keys are your minimum viable authentication. They’re simple to implement and easy for clients to use. Generate them with sufficient entropy, store them hashed, and include them in your logs for debugging. For anything handling sensitive data, think about OAuth 2.0 or JWT tokens, but start simple and evolve your security model as your requirements become clearer.

Rate limiting deserves equal attention. Without it, a single misbehaving client can bring down your entire service. Implement rate limiting early, before you need it. The classic pattern is a token bucket: allow X requests per minute, with bursts up to Y requests. Return meaningful headers like `X-Rate-Limit-Remaining` so clients can throttle themselves rather than hitting your limits blindly.

Here’s a debugging tip that will save your weekend: always include the client’s identifier in your logs. When your API starts returning 429 responses, you want to know immediately which client is causing the problem. Anonymous traffic is impossible to troubleshoot.

Versioning: Planning for Change

Your API will need to change. Requirements evolve, business logic shifts, and that field you thought was optional turns out to be critical for the mobile app’s new feature. The question isn’t whether you’ll need versioning, but how you’ll handle it without breaking existing clients.

URL-based versioning (`/v1/users`) is the most straightforward approach for REST APIs. It’s explicit, easy to understand, and plays well with caching layers. Header-based versioning is more elegant but harder to debug when things go wrong. Choose the approach that matches your team’s operational capabilities.

The real challenge isn’t technical, it’s maintaining multiple versions simultaneously. Each version you support multiplies your testing matrix and complicates your deployment process. Design your versioning strategy to minimize the number of concurrent versions you need to maintain. Look for additive changes over breaking changes wherever possible.

One pattern that’s worked well for me: maintain two versions at most, and give clients a clear migration timeline. Version N-1 gets security updates only, version N gets new features, and version N+1 is your development target. This creates pressure to migrate without leaving clients stranded.

Building your first production API is like learning to drive in city traffic. The theory only takes you so far; the real learning happens when you’re navigating real requirements with real constraints. These patterns aren’t gospel, but they’re a solid foundation that will help you avoid the most common pitfalls. Start with these fundamentals, ship something that works, and iterate based on how your clients actually use your API. The best API design happens in conversation with real usage patterns, not in isolation.

AI Romance Writers in 2026: Separating Hype From Reality

Before getting into the details, I should explain why this development matters to tech folks who understand these systems better than most.

AI Romance Writers in 2026: Separating Hype From Reality

Cutting Through the AI Writing Hype

The hype cycle moves fast enough to give you whiplash, so let me slow down before we talk about what’s actually happening here. Romance fiction is the biggest segment of the book market. Publishers and self-published authors are experimenting with AI writing tools to pump out more books and keep up with reader demand.

What I’ve found challenges how most people think about this. The numbers tell part of the story, but only part.

The reality is messier than the headlines suggest. Yes, AI writing tools have gotten better at generating romance stories that make sense. But they work within a complicated ecosystem where human creativity and tech capabilities overlap. The most successful cases use AI as an assistant while keeping humans in the editorial driver’s seat. It’s collaboration, not replacement.

Illustration for AI Romance Writers in 2026: Separating Hype From Reality

The Current Landscape of AI Romance Writing Tools

Several platforms have emerged as frontrunners in the AI romance writing space. Sudowrite AI writing tool has gained traction among fiction writers for generating solid prose and helping with writer’s block. NovelAI gives you more control over story direction and character development. Newer platforms like Blushing Reader AI story writer focus specifically on romance genre conventions.

These romance-focused platforms consistently outperform general-purpose language models when it comes to understanding genre-specific elements. They get the importance of emotional pacing, tension building, and the particular rhythms that romance readers expect. This specialization extends to recognizing common romance tropes, from enemies-to-lovers dynamics to forced proximity scenarios.

The distinction between general AI writing tools and romance-specific platforms has become increasingly important. A general-purpose AI might produce technically correct prose, but it often misses the subtle emotional beats that make romance fiction work. Dedicated romance AI tools have been trained on genre-specific datasets, so they better replicate the pacing and emotional arcs that define successful romance novels.

Technical Challenges and Limitations

Even with impressive advances, AI romance writers face significant technical hurdles. Character consistency across lengthy narratives is the biggest problem. AI can generate compelling individual scenes, but maintaining character voice, personality traits, and relationship dynamics across a 70,000-word novel? That’s tough. Characters shift personalities mid-story or forget previously established traits and histories.

This consistency problem extends beyond individual characters to world-building and plot coherence. Romance novels often have complex relationship dynamics and emotional development that requires careful tracking across multiple chapters. Current AI systems struggle with the long-term memory needed to maintain these narrative threads effectively.

Another limitation is emotional authenticity. AI can mimic the surface patterns of romantic dialogue and description, but sometimes produces interactions that feel mechanically generated rather than emotionally genuine. The subtle interplay of vulnerability, desire, and emotional growth that defines great romance often eludes current AI capabilities.

Pricing and Professional Workflows

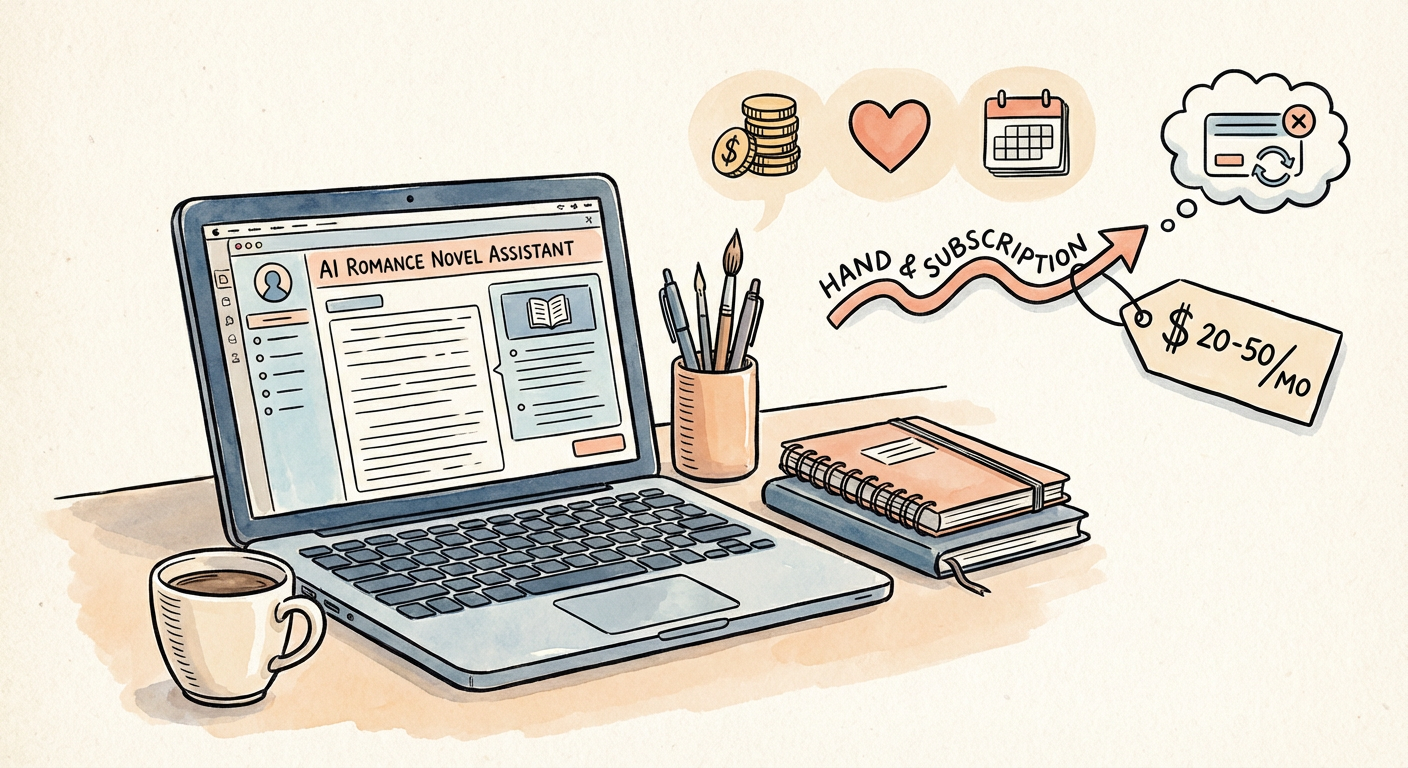
For authors considering AI assistance in their romance writing workflow, pricing has become a major factor. Subscription-based tools designed for serious self-publishing operations typically range from $20 to $50 monthly. These professional-tier services offer features like unlimited generation, advanced customization options, and higher-quality output models.

The economics make sense for authors producing multiple books per year. A $40 monthly subscription can potentially speed up writing schedules and increase publishing frequency, leading to higher overall revenue. Many successful romance authors report using AI tools to generate first drafts or overcome creative blocks, then investing substantial time in human editing and refinement.

The most effective implementations combine AI generation with human creativity and editorial judgment. Authors use AI to explore plot possibilities, generate dialogue options, or develop scene descriptions, but keep creative control over story direction and character development. This hybrid approach maximizes the efficiency gains while preserving the human elements that readers value.

Reader Reception and Quality Comparisons

Here’s what surprised me: reader feedback on AI-assisted romance fiction has been largely positive when the technology is used thoughtfully. Studies of reader responses show that AI-assisted romance novels rate comparably to human-authored category fiction in terms of entertainment value and emotional engagement. With proper human oversight, AI tools can produce commercially viable romance content.

However, this acceptance comes with important caveats. Readers respond most positively to AI-assisted works where human authors maintain creative control and use AI as a collaborative tool rather than a replacement. The most successful AI-assisted romance novels combine instruction-following capabilities with style transfer from author-provided sample text, allowing the AI to match established voice and tone preferences.

The key appears to be transparency and quality control. Readers appreciate knowing when AI assistance has been used, and they expect the same level of editing and quality assurance as traditional publishing. When these standards are met, the origin of the initial draft becomes less relevant than the final reading experience.

As the technology continues evolving, the line between AI-assisted and traditionally written romance fiction will likely blur further. The focus is shifting from whether AI should be used to how it can be integrated most effectively into creative workflows while maintaining the emotional authenticity that romance readers demand.

The specialized AI romance writing category is growing fast. Blushing Reader is an AI erotica novel writer for anyone writing in the romance or erotica space who wants a tool trained on the genre rather than a general-purpose alternative.

If you work in or around this space, the practical implications are worth mapping against your current tooling and roadmap. Try it yourself, the link is above.

The Security Blindspot Everyone’s Missing: Why Your Dependency Graph is a Ticking Time Bomb

The Iceberg Problem We’re All Ignoring

I’ve been staring at dependency graphs for the better part of two decades, and I can tell you with absolute certainty that most teams are fundamentally misunderstanding where their real security risks live. While everyone’s busy implementing zero-trust architectures and scanning Docker images, there’s a massive blindspot hiding in plain sight: the transitive dependency hell that modern applications have become.

The Security Blindspot Everyone's Missing: Why Your Dependency Graph is a Ticking Time Bomb
The Security Blindspot Everyone’s Missing: Why Your Dependency Graph is a Ticking Time Bomb

Your average React app pulls in roughly 1,400 packages. Your typical Node.js backend? Easily 800+. Each one of those packages has its own dependencies, and those have dependencies, creating a fractal nightmare of potential attack vectors. The math is brutal. That innocent-looking `npm install` you ran yesterday just invited approximately 50,000 lines of third-party code into your production environment, and you probably reviewed exactly zero percent of it.

The real kicker? Most security tools are still playing catch-up with this reality. They’ll happily scan your first-level dependencies and give you a green checkmark. Meanwhile, they’re completely blind to what’s happening six levels deep. There’s probably a package in there that’s maintained by one overworked developer in their spare time. And it hasn’t been updated since the Obama administration.

Illustration for The Security Blindspot Everyone's Missing: Why Your Dependency Graph is a Ticking Time Bomb
Illustration for The Security Blindspot Everyone’s Missing: Why Your Dependency Graph is a Ticking Time Bomb

The Supply Chain Attack Renaissance

Remember when we used to worry about SQL injection and XSS? Those were simpler times. Today’s attackers have figured out something far more elegant: why break into the house when you can become the locksmith? Supply chain attacks have exploded because they’re devastatingly effective and surprisingly easy to execute.

The `event-stream` incident in 2018 was a masterclass in this approach. A popular npm package with millions of weekly downloads was compromised through a seemingly innocent dependency update. The attacker didn’t need to find a zero-day or exploit a buffer overflow. They just needed patience and social engineering skills. They offered to help maintain an open-source project, gained trust over time, then introduced a malicious dependency that specifically targeted cryptocurrency wallets.

What makes this particularly insidious is the blast radius. When you compromise a widely-used utility library, you’re not attacking one application. You’re attacking every application that depends on it, and every application that depends on something that depends on it. It’s the software equivalent of poisoning the water supply.

The attack surface has grown exponentially, but our defensive thinking hasn’t evolved to match. We’re still applying perimeter-based security models to a world where the perimeter dissolved years ago.

The Hidden Gems in Security Tooling

While the industry catches up, there are some genuinely impressive tools emerging that tackle this problem head-on. Socket Security has built something remarkable: real-time analysis of npm packages that goes beyond static vulnerability scanning. They’re actually analyzing package behavior, looking for suspicious network calls, filesystem access, and shell execution. It’s like having a paranoid security engineer review every package in your dependency tree, except it actually scales.

Another tool that’s been flying under the radar is Snyk’s container scanning, but specifically their approach to base image recommendations. Instead of just telling you what’s vulnerable, they’ll suggest alternative base images that reduce your attack surface while maintaining compatibility. It’s the difference between “your house has security problems” and “here’s a better neighborhood to move to.”

For the command-line aficionados, `npm audit` and `yarn audit` have quietly become incredibly sophisticated. The latest versions don’t just identify vulnerabilities, they’ll automatically apply patches when available and provide detailed remediation guidance. Combined with tools like `audit-ci`, you can fail builds based on vulnerability severity thresholds. It’s not glamorous, but it works.

The most interesting development, though, is the emergence of Software Bill of Materials (SBOM) tooling. Projects like Syft and CycloneDx are making it trivial to generate comprehensive inventories of your software components. When the next major supply chain attack hits, you’ll know within minutes whether you’re affected instead of spending days playing dependency archaeology.

The Real-World Implementation Strategy

Here’s what actually works in production, based on surviving more late-night security incidents than I care to remember. First, dependency pinning is non-negotiable. Lock files are your friend, but they’re not enough. You need to pin to specific versions and treat updates as deliberate, reviewable events rather than automatic background processes.

Second, implement staged dependency updates with automated testing at each layer. Your CI pipeline should run a full test suite against dependency updates in an isolated environment before they ever reach production. I’ve seen too many teams get burned by “minor” updates that introduced breaking changes or, worse, malicious code.

Third, establish dependency hygiene practices. Regular dependency audits shouldn’t be a quarterly ritual, they should be part of your weekly workflow. Set up automated alerts for new vulnerabilities in your dependency tree. Most importantly, maintain an active inventory of what you’re actually using versus what you’ve installed. Dead dependencies are security liabilities with zero upside.

The nuclear option, which I’ve implemented in particularly security-sensitive environments, is dependency source auditing. For critical applications, we actually review the source code of our direct dependencies and their immediate children. It’s labor-intensive, but it’s also how you catch supply chain attacks before they catch you.

The Automated Defense Future

The trajectory here is clear: manual dependency management is going extinct. The scale and complexity have outgrown human capability. The next generation of security tooling is moving toward automated policy enforcement, behavioral analysis, and predictive threat modeling.

Machine learning models are getting genuinely good at identifying suspicious code patterns in dependencies. GitHub’s CodeQL and similar tools can flag potential security issues in code that hasn’t even been identified as a vulnerability yet. We’re moving from reactive patching to proactive threat prevention.

The most promising development is the integration of security scanning directly into the development workflow. IDE plugins that highlight risky dependencies as you type, pre-commit hooks that block dangerous packages, and automated pull requests that remove unused dependencies. Security is finally becoming a first-class citizen in the development process rather than an afterthought.

If you’re not already thinking about dependency security as a core part of your application security strategy, you’re behind. The good news is that the tooling has finally caught up to the problem. The better news is that implementing these practices doesn’t require a complete rebuild of your development workflow. Start with automated dependency scanning, add SBOM generation to your build process, and gradually layer in more sophisticated defenses. Your future self will thank you when you’re not debugging a supply chain incident at 3 AM.

The Monolith vs Microservices Decision: A Beginner’s Guide to Not Shooting Yourself in the Foot

Start With What Works, Not What’s Trendy

Every few years, the industry collectively decides that everything we’ve been doing is wrong and latches onto the next silver bullet. Right now, that bullet happens to be microservices. Before you tear apart your perfectly functional application to chase the latest architectural pattern, let’s talk about what actually matters for your project.

The Monolith vs Microservices Decision: A Beginner's Guide to Not Shooting Yourself in the Foot
The Monolith vs Microservices Decision: A Beginner’s Guide to Not Shooting Yourself in the Foot

Here’s the dirty secret about microservices: most companies implementing them don’t actually need them. They’re solving for problems they don’t have while creating problems they definitely don’t want. Netflix didn’t wake up one day and decide microservices would be fun. They evolved into them because their monolith was literally killing their ability to deploy code without taking down the entire platform.

If you’re building your first real application or working on a team smaller than 20 engineers, start with a monolith. Not because microservices are bad, but because you have bigger fish to fry than distributed system complexity. Focus on building something people actually want to use first. The architecture can evolve later when you have real problems to solve instead of theoretical ones.

Illustration for The Monolith vs Microservices Decision: A Beginner's Guide to Not Shooting Yourself in the Foot
Illustration for The Monolith vs Microservices Decision: A Beginner’s Guide to Not Shooting Yourself in the Foot

When Monoliths Actually Break Down

A well-structured monolith can scale surprisingly far before it becomes a genuine problem. I’ve seen single Rails applications handle millions of requests per day with proper caching, database optimization, and horizontal scaling. The breaking point isn’t usually technical performance, though. It’s organizational complexity.

The real pain starts when you have multiple teams stepping on each other’s toes in the same codebase. When a change to the billing module requires coordination with the inventory team, who needs to check with the shipping folks before anyone can deploy, you’ve hit the organizational scaling wall. Conway’s Law stops being an academic observation and becomes a daily nightmare.

Database contention becomes another genuine issue as your application grows. When every feature requires touching the same core tables, you end up with increasingly complex migration coordination and deployment orchestration. Your database becomes a bottleneck not just for performance but for development velocity.

Technical debt accumulation in a large monolith can reach a tipping point where even simple changes require understanding vast swaths of interconnected code. When adding a new field to a user profile requires changes in 47 different files across 8 different modules, and nobody is quite sure what all those changes do, you might be ready for a different approach.

The Microservices Reality Check

Microservices solve specific problems, but they create entirely new categories of complexity that most developers have never dealt with. Network partitions, service discovery, distributed tracing, eventual consistency, and cascading failures become your daily reality instead of academic concepts you read about in blog posts.

The operational overhead alone can sink teams that aren’t prepared for it. You’re now running multiple services, each with their own deployment pipelines, monitoring, logging, and debugging requirements. That simple database query you used to write? Now it might involve calls to three different services, each with their own failure modes and retry logic.

Testing becomes exponentially more complex when your business logic spans multiple services. Integration testing requires spinning up multiple services or creating increasingly complex mocks. The feedback loop between writing code and seeing it work gets longer, which kills developer productivity faster than almost anything else.

The cognitive load of understanding how data flows through your system increases dramatically. Instead of following a single call stack through your monolith, you’re tracing requests across service boundaries, dealing with asynchronous messaging, and debugging issues that only appear under specific timing conditions in production.

A Practical Migration Strategy

If you’ve determined that microservices actually solve problems you have, the migration strategy matters more than the destination. The strangler pattern works well for gradually extracting services from a monolith without requiring a complete rewrite. Start by identifying bounded contexts within your application that have clear data ownership and minimal cross-cutting concerns.

Begin with read-only services or features that naturally sit at the edges of your system. User notifications, reporting services, or file processing workflows often make good candidates for extraction because they have well-defined inputs and don’t require complex transactional coordination with the rest of your system.

Invest heavily in your deployment and monitoring infrastructure before you start extracting services. You’ll need robust health checks, circuit breakers, distributed tracing, and centralized logging just to maintain the operational visibility you had with your monolith. This infrastructure work isn’t glamorous, but it’s what separates successful microservices adoptions from the horror stories.

Consider hybrid approaches that capture some benefits of microservices without the full complexity. Services that share databases can avoid distributed transaction complexity while still providing deployment isolation. Message queues can provide asynchronous communication patterns without requiring full service extraction.

Making the Right Choice for Your Context

The monolith versus microservices decision shouldn’t be based on what’s trending on Hacker News or what the big tech companies are doing. Your context matters more than their war stories. Team size, organizational structure, domain complexity, and operational maturity all factor into what will actually work for your specific situation.

Small teams building greenfield applications should almost always start with a well-structured monolith. Focus on getting the domain boundaries right, writing comprehensive tests, and building deployment automation. These investments pay dividends whether you stick with the monolith or eventually extract services from it.

Large organizations with multiple teams working on clearly separated business domains might benefit from microservices, but only if they’re prepared to invest in the operational infrastructure and organizational changes required to make them successful. Half-hearted microservices adoptions create the worst of both worlds: monolith complexity plus distributed system headaches.

The best architectural decisions are boring ones that solve real problems without creating unnecessary complexity. Sometimes that’s a monolith. Sometimes it’s microservices. Most of the time, it’s something in between that evolves organically as your understanding of the problem space matures. If you’re wrestling with these decisions in your own projects, I’d love to hear about your specific context and challenges in the comments below.