The AI Code Review Paradox: How GitHub’s Latest Tool Is Creating a Generation of Developers Who Can’t Debug Their Own Code

The Uncomfortable Truth About Our AI-Assisted Future

After fifteen years of watching junior developers evolve from copy-pasting Stack Overflow snippets to wielding AI assistants like digital Swiss Army knives, I’ve noticed something unsettling. GitHub’s new AI code review assistant has attracted 2.3 million active users in just three months, with an overwhelming 67% being developers with less than three years of experience. That’s not inherently problematic. What keeps me up at night is what happens when these developers hit production issues that their AI assistant can’t solve.
The AI Code Review Paradox: How GitHub's Latest Tool Is Creating a Generation of Developers Who Can't Debug Their Own Code
The AI Code Review Paradox: How GitHub’s Latest Tool Is Creating a Generation of Developers Who Can’t Debug Their Own Code

The pattern became clear during a recent incident at 2 AM when a junior engineer on my team couldn’t trace a memory leak through code they’d written with AI assistance just weeks earlier. They could describe what the code was supposed to do but couldn’t explain why it was consuming 400MB per request. When your AI co-pilot becomes your primary navigator, you never learn to read the map yourself.

The Stack Overflow 2025 Developer Survey confirmed what many of us have observed firsthand: 43% of junior developers using AI assistants couldn’t adequately explain core algorithms they’d implemented. These aren’t esoteric computer science concepts. We’re talking about basic sorting algorithms, data structure traversals, and fundamental design patterns that form the bedrock of software engineering.
Illustration for The AI Code Review Paradox: How GitHub's Latest Tool Is Creating a Generation of Developers Who Can't Debug Their Own Code
Illustration for The AI Code Review Paradox: How GitHub’s Latest Tool Is Creating a Generation of Developers Who Can’t Debug Their Own Code

When AI Reviews Replace Human Understanding

Microsoft’s latest metrics show that teams using GitHub’s AI review tools caught 34% fewer critical bugs during human code review sessions. On the surface, this looks like a win for automation. Dig deeper, and you’ll find the real story: human reviewers are becoming complacent, assuming the AI has already caught the important issues. The result is a dangerous blind spot where both human intuition and AI pattern matching fail simultaneously.

I’ve witnessed this firsthand during code reviews where junior developers present AI-generated solutions they clearly don’t understand. When I ask probing questions about edge cases or performance implications, I’m often met with blank stares or responses like “the AI said this was the best approach.” The problem isn’t that the AI is wrong. The problem is that the developer has given up their responsibility to understand their own code.

Carnegie Mellon’s recent study drives this point home with uncomfortable precision. Junior developers who relied heavily on AI tools scored 28% lower on independent coding assessments compared to their peers who used traditional learning methods. These weren’t trick questions or academic puzzles. These were practical programming challenges that any competent developer should handle confidently after two years of experience.

The most damaging aspect isn’t the immediate performance gap. It’s the confidence gap that follows. Developers who can’t debug their own AI-assisted code begin to doubt their fundamental abilities, creating a vicious cycle where they become even more dependent on AI tools for basic tasks they should have mastered months ago.

The Technical Debt Time Bomb

Atlassian’s engineering team documented something that should terrify every senior engineer: a 45% increase in technical debt when junior developers relied heavily on AI code generation without adequate senior oversight. This isn’t just about messy code or inconsistent naming conventions. We’re talking about architectural decisions that compound over months, creating systems that become increasingly difficult to maintain, extend, or debug.

AI assistants excel at producing syntactically correct code that solves immediate problems, but they lack the contextual understanding to make decisions that help long-term system health. A junior developer might ask an AI to implement user authentication and receive perfectly functional code that introduces three new dependencies, bypasses the existing security framework, and creates a maintenance nightmare for future teams. The AI delivered exactly what was requested, but the developer lacked the experience to request the right thing.

The GitHub Copilot Workspace documentation emphasizes collaboration between human intelligence and AI capabilities, but the reality in most organizations is that junior developers are operating these tools without sufficient guardrails or mentorship. The result is code that works in the short term but creates exponentially more work for senior engineers down the line.

Building Better Developers in the AI Era

The solution isn’t to abandon AI tools. That ship has sailed, and trying to turn back the clock would be both futile and counterproductive. Instead, we need to fundamentally rethink how we onboard and mentor junior developers in an AI-enhanced world. The goal should be creating developers who can leverage AI effectively while maintaining deep technical understanding.

Start by establishing AI-free zones in your development process. Require junior developers to implement core algorithms from scratch before they’re allowed to use AI assistance. Make them trace through their own code line by line during code reviews. When they present AI-generated solutions, don’t just verify that the code works. Ask them to explain the underlying principles, identify potential failure modes, and propose alternative approaches.

Implement pair programming sessions where senior engineers work alongside junior developers, not just reviewing their final output but observing their problem-solving process in real time. This reveals gaps in understanding that wouldn’t surface during traditional code reviews. When a junior developer immediately reaches for an AI assistant to solve a basic problem, that’s a teachable moment.

Create debugging challenges using code that AI assistants typically generate. Present junior developers with AI-written code that contains subtle bugs or performance issues, and have them identify and fix the problems without AI assistance. This builds the critical thinking skills they’ll need when their AI tools inevitably fall short.

The Path Forward for Senior Engineers

We’re at a crossroads where our response will shape the next generation of developers. We can either embrace our role as technical mentors who help junior engineers navigate the AI landscape thoughtfully, or we can give up that responsibility and deal with the consequences later. The choice seems obvious, but it requires intentional effort and a willingness to slow down short-term delivery in service of long-term technical excellence.

The most successful teams I’ve observed treat AI tools like powerful but potentially dangerous equipment. Junior developers earn the privilege of using these tools by first demonstrating mastery of fundamental concepts. They learn to prompt AI assistants effectively because they understand what good code looks like. They catch AI-generated bugs because they’ve trained their instincts through hands-on experience with similar problems.

This isn’t about gatekeeping or nostalgic attachment to “the old ways.” It’s about ensuring that the developers we’re training today will be capable of building and maintaining the complex systems that tomorrow’s problems will demand. AI will continue to evolve and improve, but the need for developers who can think critically about code, debug complex systems, and make sound architectural decisions will never disappear.

What strategies have you found effective for mentoring junior developers in your AI-enhanced development environment? I’d love to hear about both your successes and your failures as we collectively navigate this transition.
Why Your Distributed System Debugs Like a Crime Scene Investigation

The 3 AM Production Fire That Taught Me Everything

The alert came in at 2:47 AM. Customer orders were timing out across three availability zones. Our monitoring dashboard looked like a Christmas tree having a seizure. The incident response channel filled with engineers throwing around theories: network partitions, database locks, cache invalidation cascades. Everyone had a hunch. Nobody had evidence.

Two hours later, we discovered the root cause was a single misconfigured load balancer health check that was marking healthy instances as unhealthy, triggering a cascade of automated scaling events that overwhelmed our message queue. The symptoms pointed everywhere except the actual problem. That night taught me something I’d suspected for years: debugging distributed systems isn’t about following breadcrumbs. It’s about reconstructing a crime scene where the evidence is scattered across dozens of machines, and half the witnesses have already been recycled by auto-scaling groups.

Your Mental Model is Wrong (And So Was Mine)

Most engineers approach distributed debugging with a monolithic mindset. We look for the smoking gun, the obvious bottleneck, the single point of failure. This works great for debugging a recursive function or tracking down a memory leak in a single process. It fails spectacularly when your “application” is actually 47 microservices communicating through 6 different protocols across 3 cloud providers.

You need to accept that causality in distributed systems is probabilistic, not deterministic. That timeout you’re seeing might be caused by increased latency three hops upstream, a gradual memory leak that only shows up under specific load patterns, or a race condition that only triggers when two particular services scale at the same time. The symptom and the cause exist in different dimensions of your system’s state space.

I learned this the hard way debugging a payment processing system where transaction failures spiked every Tuesday at 2 PM. After weeks of investigation, we discovered that a batch job on an entirely separate system was consuming database connection pool resources, causing cascading timeouts in our payment service. The two systems shared nothing except a database cluster. The connection was invisible until you mapped resource consumption patterns across time.

Observability Is Not Monitoring (Stop Confusing Them)

Your Grafana dashboards are beautiful. Your alerting rules are comprehensive. You have SLOs for everything that moves. Congratulations, you have monitoring. What you probably don’t have is observability, and the difference matters when you’re neck-deep in a production incident that doesn’t fit any of your pre-conceived failure modes.

Monitoring tells you what’s happening. Observability tells you why. Monitoring is your smoke detector, observability is your forensic laboratory. When I see engineering teams with hundreds of metrics dashboards but no distributed tracing, no structured logging strategy, and no correlation IDs threading through their request flows, I know they’re optimizing for the wrong thing. They’re building beautiful rear-view mirrors for a race car that’s about to hit a wall they can’t see.

The most effective distributed debugging setup I’ve seen used OpenTelemetry to instrument every service boundary, Jaeger for distributed tracing, and a centralized logging system with structured JSON that included correlation IDs, user context, and service topology information. When something broke, they could reconstruct the entire request flow across 20+ services in under five minutes. The initial instrumentation overhead was significant, but the debugging velocity improvement was transformative.

Correlation vs Causation (The False Prophet of Load Testing)

Here’s where most teams go wrong: they see a correlation between high CPU usage and increased error rates, so they assume CPU is the problem. They throw more compute at it. Errors decrease temporarily. Problem solved, right? Wrong. They’ve treated a symptom while the underlying issue gets worse.

I once debugged a system where response times degraded linearly with request volume, textbook resource contention behavior. The obvious solution was horizontal scaling. We doubled the instance count. Performance improved for exactly 48 hours, then degraded again. We scaled again. Same pattern. The real issue was a database query that performed a full table scan on a rapidly growing table. More application instances meant more concurrent scans, eventually overwhelming the database regardless of application-tier capacity.

Load testing makes this worse because it rarely reproduces real-world access patterns. Your synthetic traffic hits all the happy paths with perfectly distributed timing. Real users create hot spots, edge cases, and cascading dependencies that your load tests never discovered. I’ve seen systems handle 10x their expected load in testing then collapse under normal production traffic because a single user’s workflow triggered a pathological query pattern.

The Tools That Actually Move the Needle

Forget the vendor pitches. After debugging production systems for over a decade, here’s what actually works when everything is on fire and management is breathing down your neck.

Distributed tracing isn’t optional anymore. Start with OpenTelemetry and Jaeger. Yes, the initial setup is painful. Yes, it adds latency. No, you can’t afford not to have it. The ability to see a request’s entire journey across service boundaries is the difference between guessing and knowing. I’ve resolved week-long debugging sessions in hours once we had proper trace data.

Structured logging with correlation IDs is your second line of defense. Every log entry should include request ID, user context, service version, and enough contextual information to reconstruct the system state. Use JSON format, not pretty-printed messages. Your log aggregation system needs to parse this data, not your eyeballs. ELK stack or equivalent is table stakes.

Circuit breakers and timeout configurations that actually make sense. Most teams set arbitrary timeout values that feel reasonable but have no basis in actual performance characteristics. Measure your 99th percentile response times under load, then set timeouts at 2-3x that value. Circuit breakers should fail fast and provide meaningful error messages, not generic “service unavailable” responses that tell you nothing about why the failure occurred.

The Uncomfortable Truth About Complexity

Every distributed system eventually becomes too complex for any individual to fully understand. This isn’t a failure of engineering, it’s what happens when systems grow to serve real business requirements. The question isn’t how to avoid this complexity, but how to maintain debuggability as complexity increases.

The most effective teams I’ve worked with accept this reality and build debugging capabilities into their architecture from day one. They don’t bolt on observability after the system is already incomprehensible. They design service interfaces with debugging in mind, implement chaos engineering practices to surface failure modes before customers do, and most importantly, they document not just what their systems do, but why they were designed that way.

The next time you’re staring at a distributed system misbehaving in ways that seem to defy physics, remember that you’re not debugging code. You’re investigating an emergent behavior that arose from the interaction of dozens of components, each operating correctly in isolation. Your job isn’t to find the bug, it’s to understand the system well enough to predict where bugs hide.

Why Meta’s Code Llama 3 Still Can’t Replace Your Senior Developer: A Reality Check on AI Pair Programming

The Morning After the AI Revolution

Three months ago, our engineering team got swept up in the latest wave of AI coding assistants, with Meta’s Code Llama 3 promising to change everything about how we write software. The benchmarks looked impressive, the demos were slick, and management was asking pointed questions about developer productivity. So we dove in headfirst, expecting our junior developers to suddenly write senior-level code and our seniors to become unstoppable coding machines.

Why Meta's Code Llama 3 Still Can't Replace Your Senior Developer: A Reality Check on AI Pair Programming
Why Meta’s Code Llama 3 Still Can’t Replace Your Senior Developer: A Reality Check on AI Pair Programming

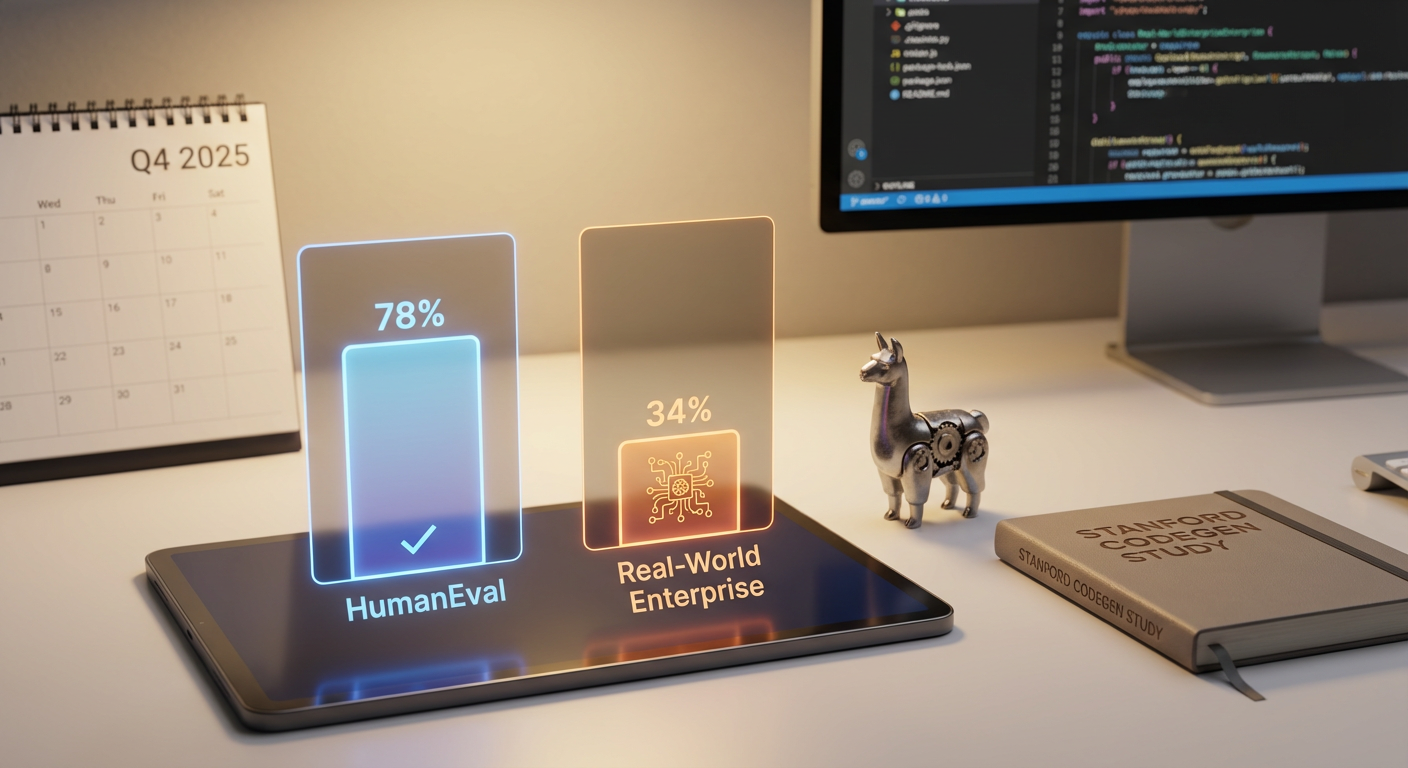
What we discovered instead was a sobering lesson in the difference between controlled environments and the chaotic reality of enterprise software development. While Code Llama 3 hit 78% accuracy on HumanEval benchmarks, the Stanford CodeGen Research Study showed a harsh truth: that same model managed only 34% accuracy when unleashed on real-world enterprise codebases. The gap between academic benchmarks and production reality turned out to be a chasm wide enough to swallow entire sprint commitments.

The honeymoon period was brief but intoxicating. For the first few weeks, our developers marveled at the AI’s ability to generate boilerplate code, suggest function implementations, and even help with documentation. The productivity gains felt real. Then we started hitting edge cases, legacy system integrations, and the kind of gnarly business logic that makes you question your career choices at 2 AM.

Illustration for Why Meta's Code Llama 3 Still Can't Replace Your Senior Developer: A Reality Check on AI Pair Programming
Illustration for Why Meta’s Code Llama 3 Still Can’t Replace Your Senior Developer: A Reality Check on AI Pair Programming

When the Magic Wears Off

The disillusionment started small. A suggested function that looked perfect but failed to handle our specific data validation requirements. An elegant algorithm that completely ignored our established error handling patterns. Database queries that worked in isolation but created deadlocks when integrated with our existing transaction management. Each incident required more debugging time than writing the original code would have taken.

This pattern isn’t unique to our team. The GitHub’s 2025 Developer Experience Report revealed that Copilot usage among teams with five or more years of experience dropped by 23% after the initial six-month adoption period. The veterans figured out what we learned the hard way: AI-generated code often creates more problems than it solves when you’re dealing with complex, interconnected systems.

The most experienced developers on our team became increasingly selective about when and how they used AI assistance. They learned to treat it like sophisticated autocomplete rather than a coding partner, useful for generating test cases or exploring API documentation but unreliable for anything requiring deep system knowledge or nuanced business logic understanding.

Meanwhile, our junior developers fell into a different trap. They became overly dependent on AI suggestions, losing opportunities to develop critical thinking skills about code architecture and design patterns. When the AI produced plausible-looking but fundamentally flawed solutions, they lacked the experience to spot the problems before committing to version control.

The Debug Tax Nobody Talks About

Stack Overflow’s latest survey dropped a statistic that made our entire engineering leadership team pause: 67% of developers now spend more time debugging AI-generated code than writing original solutions for complex business logic. This matches our experience perfectly. What should have been productivity multipliers became productivity drains, especially when dealing with the complex requirements that define enterprise software.

The debugging challenge with AI-generated code is particularly tricky because the code often looks correct at first glance. It follows proper syntax, uses reasonable variable names, and implements what appears to be sound logic. The problems emerge during integration, under load, or when edge cases expose assumptions the AI made about data structures, user behavior, or system constraints.

We tracked our debugging time carefully for eight weeks. For straightforward implementations like CRUD operations or simple API integrations, AI assistance provided genuine time savings. But for anything involving complex business rules, multi-service orchestration, or performance-critical operations, the debug-to-development ratio inverted. We spent more time understanding and fixing AI suggestions than we would have invested in thoughtful, deliberate implementation from scratch.

The security implications added another layer of complexity. Anthropic’s Claude 3.5 Sonnet, during beta testing at major enterprises, showed a 45% false positive rate when suggesting security fixes in production environments. These weren’t minor oversights but fundamental misunderstandings of authentication flows, data validation requirements, and authorization patterns specific to each organization’s security model.

The Human Element That AI Still Missing

The most telling metric came from Microsoft’s internal DevOps analysis: OpenAI’s GPT-4 Turbo code generation requires an average of 2.3 human review cycles before reaching deployment readiness. This isn’t a failure of the technology so much as a recognition that software development involves far more than translating requirements into syntactically correct code.

Senior developers bring context that no AI model currently possesses. They understand the historical decisions that shaped the current architecture, the performance characteristics of different implementation approaches, and the subtle interdependencies that make seemingly simple changes ripple through multiple system components. They know which shortcuts will create technical debt and which optimizations will actually matter in production.

More importantly, experienced developers excel at asking the right questions before writing any code at all. They challenge requirements, propose alternative approaches, and identify potential issues that requirements documents never capture. AI coding assistants, no matter how sophisticated, remain fundamentally reactive tools that generate solutions to problems as stated rather than questioning whether those problems are worth solving in the first place.

The nuanced understanding of trade-offs is another irreplaceable human capability. Should this function prioritize memory efficiency or execution speed? How should error conditions bubble up through the application layers? What level of abstraction helps future maintainability without over-engineering current requirements? These decisions require experience, judgment, and deep understanding of both technical and business contexts that extend far beyond pattern recognition and code generation.

Finding the Right Partnership Model

After months of experimentation, we’ve settled into a more pragmatic relationship with AI coding tools. They excel as research assistants, helping explore unfamiliar APIs or generating comprehensive test scenarios. They’re invaluable for documentation tasks and can quickly prototype multiple implementation approaches for comparison. But they remain tools that amplify human capabilities rather than replace human judgment.

The most successful AI integration happened when our senior developers used these tools strategically rather than reflexively. They used AI for rapid exploration of solution spaces, then applied their experience and domain knowledge to select and refine the most promising approaches. This combination of AI-powered generation and human-guided curation proved far more effective than either pure AI assistance or traditional manual development.

We also discovered that AI coding tools work best within well-established architectural patterns and coding standards. When the surrounding codebase provides clear examples and consistent conventions, AI suggestions align more closely with project requirements and team expectations. The tools struggle most in greenfield projects or legacy systems where patterns are inconsistent and context is king.

The reality is that Meta’s Code Llama 3, like all current AI coding assistants, is an impressive but fundamentally limited tool in the software development toolkit. It can accelerate certain types of work and provide valuable assistance with routine tasks, but it cannot replace the strategic thinking, contextual knowledge, and hard-earned wisdom that define truly senior-level development work. The future likely belongs to developers who learn to wield these tools effectively rather than those who expect to be replaced by them.

Why I Spent Three Months Reading Redis Source Code (And You Should Too)

The 3 AM Debugging Session That Changed Everything

Picture this: production is melting down, your cache hit rates have plummeted to single digits, and you’re staring at Redis logs that might as well be written in ancient Sumerian. I’d been using Redis for years, treating it like a magical black box that stored my key-value pairs and occasionally got cranky. That night, fumbling through Stack Overflow answers and Redis documentation, I realized something embarrassing: I had no idea how this thing actually worked.

Three months later, after digging deep into Redis source code, I understood not just what Redis does, but how it thinks. More importantly, I discovered that reading production-grade open source code is probably the fastest way to level up as an engineer. Redis turned out to be the perfect teacher because its codebase is surprisingly readable, well-commented, and solves real problems you encounter every day.

Start With the Data Structures (They’re Simpler Than You Think)

Redis calls itself a “data structure server,” and that’s exactly where you should begin your exploration. Start with src/sds.c – the Simple Dynamic Strings implementation. You’ll find a clever twist on C strings that avoids the performance pitfalls of strlen() by storing the length in a header. It’s elegant, practical, and you can understand the entire file in an afternoon.

Next, crack open src/ziplist.c. Redis uses ziplists to store small sorted sets and hashes efficiently. The comments read like a friendly engineering discussion, explaining why they chose this memory-compact encoding and when it makes sense to upgrade to more complex structures. You’ll see real engineering tradeoffs in action: space versus time, simplicity versus flexibility.

Don’t try to understand everything at once. Pick one data structure, build a small test program that uses it, and watch how Redis behaves with MEMORY USAGE and DEBUG OBJECT commands. The “aha” moments come when you can predict Redis’s internal behavior just by looking at your data patterns.

Follow the Event Loop (Where the Magic Happens)

Redis is single-threaded, which sounds insane until you see how it actually works. The event loop lives in src/ae.c (Async Event), and it’s a masterclass in non-blocking I/O. Start by tracing a simple GET request from socket to response. You’ll discover that Redis doesn’t block waiting for disk or network. It juggles thousands of connections by handling whatever’s ready right now.

The networking layer in src/networking.c shows how Redis batches writes and handles partial reads gracefully. Notice how it never allocates memory in the hot path if it can help it. This isn’t just academic knowledge. Understanding this helped me debug a production issue where our application was overwhelming Redis with tiny, frequent writes instead of batching them sensibly.

Build a simple echo server using the same patterns. You don’t need Redis’s complexity, but implementing a basic event loop with epoll or kqueue will give you intuition for how Redis scales to handle massive workloads on modest hardware. Your respect for Redis’s architecture will grow exponentially.

Dig Into Persistence (Because Durability Matters)

Redis offers two persistence strategies: RDB snapshots and AOF logs. The RDB implementation in src/rdb.c shows how to serialize complex in-memory structures to disk efficiently. Redis doesn’t just dump memory. It uses a compact binary format that handles different data types intelligently. Follow how a sorted set gets encoded versus a simple string, and you’ll appreciate the engineering that goes into making persistence both fast and space-efficient.

The AOF (Append Only File) code in src/aof.c takes a different approach: log every write command. The rewrite logic is particularly clever. Redis can compress years of operations into a minimal set of commands that recreate the current state. Try experimenting with AOF rewriting on a test instance loaded with realistic data patterns from your application.

Understanding persistence internals pays immediate dividends. You’ll stop cargo-culting Redis configuration and start making informed decisions about RDB versus AOF based on your actual recovery time objectives and data loss tolerance. More importantly, you’ll recognize similar patterns in other systems and know when to apply them in your own designs.

Your Three-Month Journey Starts With One File

Don’t aim to understand everything immediately. Pick one aspect that interests you, maybe the clever memory management in src/zmalloc.c, or the surprisingly sophisticated client tracking in src/tracking.c. Read the code, run experiments, break things safely in a test environment. Keep a learning journal of interesting patterns and design decisions you discover.

The Redis codebase isn’t just about caching. It’s a graduate course in systems programming disguised as a weekend side project. You’ll encounter memory pools, binary protocols, background job scheduling, and dozens of other concepts that transfer directly to your day job. Plus, Redis’s code is unusually well-commented, making it an ideal choice for your first deep dive into a major open source project.

Set up a development environment, compile Redis from source, and start poking around. The next time production breaks at 3 AM, you might actually understand what’s happening under the hood. And who knows? You might even find yourself contributing back to the project that taught you so much.

Why Your Framework Choice Probably Matters Less Than Your Team Thinks

The Monday Morning Architecture Meeting

Picture this: you’re sitting in a conference room at 9 AM, clutching your third cup of coffee, while someone draws boxes and arrows on a whiteboard explaining why React’s virtual DOM will solve all your performance problems. Meanwhile, the guy who’s been maintaining the Vue.js admin panel for two years looks like he’s contemplating a career change to sheep farming. This scene plays out in tech companies every week, and it’s usually missing the point entirely.

Framework architecture discussions focus on the wrong metrics. We obsess over bundle sizes, rendering speeds, and developer experience scores while ignoring the fact that most applications spend 80% of their time waiting for network requests. The real question isn’t which framework has the prettiest component model. It’s which one your team can actually ship working software with, debug at 2 AM, and hand off to the next developer without requiring a PhD in computer science.

Component Models: The Good, The Weird, and The Overengineered

React’s component model feels like writing JavaScript that happens to produce HTML. Vue feels like writing HTML that happens to run JavaScript. Angular feels like writing TypeScript that happens to be a web framework. These aren’t bugs, they’re design philosophies, and each one attracts different kinds of problems and different kinds of developers.

React’s functional components with hooks solved the class component mess, but introduced a whole new category of mental overhead. Try explaining useEffect’s dependency array to a junior developer without using the phrase “it’s complicated.” Vue’s single-file components are genuinely pleasant to work with until you need to share logic between components and discover that mixins were deprecated, composables are the new hotness, but half your team is still using the options API because “it’s more readable.”

Angular took the “let’s solve everything” approach and mostly succeeded, which is both impressive and exhausting. You get dependency injection, observables, decorators, and a CLI that generates more boilerplate than a 1990s Java enterprise application. It works brilliantly for large teams who want guardrails everywhere. It’s overkill for everything else, but overkill that scales predictably.

State Management: Where Good Intentions Go to Die

Redux promised predictable state management and delivered predictable amounts of boilerplate. Want to update a user’s email address? Write an action creator, a reducer, connect your component, and dispatch the action. That’s four files for what should be one line of code. The Redux Toolkit improved things considerably, but the fundamental question remains: do you really need global state management for a todo app?

Vue’s Pinia and Angular’s services represent different philosophies. Pinia feels like Vuex without the ceremony, letting you write stores that look like regular JavaScript objects with reactive properties. Angular’s services with RxJS give you the power to compose complex data flows, assuming you enjoy thinking in streams and operators. Both approaches work well until someone decides to mutate state directly and your application enters a quantum superposition of working and broken.

The dirty secret is that most applications don’t need sophisticated state management. Server state belongs in a cache like React Query or SWR. Client state is usually just form data and UI flags. The elaborate state machines we build are often solutions to problems we created by overthinking simpler problems.

Performance Theater vs. Actual Performance

Bundle size analyzers have created a generation of developers who can tell you exactly how many kilobytes their framework adds while ignoring the 2MB of images loading on every page. Svelte’s compiler produces smaller bundles than React, but your users won’t notice the difference if you’re loading 47 analytics scripts and a chat widget that downloads its own copy of jQuery.

Virtual DOM diffing is genuinely clever engineering, but it’s solving a problem that mostly doesn’t exist in well-architected applications. If you’re updating thousands of DOM nodes on every render, you have bigger problems than framework choice. Vue’s proxy-based reactivity and Svelte’s compile-time optimizations are technically superior, but the performance difference vanishes under the weight of poorly optimized API calls and uncompressed assets.

The real performance bottlenecks are usually network waterfalls, blocking JavaScript execution, and layout thrashing from CSS changes. Pick any modern framework, implement proper code splitting, and optimize your critical rendering path. The framework overhead will be lost in the noise of everything else your application is doing wrong.

Developer Experience: The Hidden Productivity Multiplier

TypeScript integration tells you everything about a framework’s maturity. React’s types are maintained by the community and occasionally drift out of sync with reality. Vue 3’s TypeScript support is excellent but feels bolted on rather than fundamental. Angular was built with TypeScript from day one, which shows in both the excellent tooling and the occasionally verbose type annotations.

Error messages matter more than benchmark scores. Svelte’s compile-time error messages are genuinely helpful. Vue’s runtime warnings point you toward the actual problem. React’s error boundaries are powerful but require you to implement them yourself. Angular’s error messages are comprehensive but sometimes read like academic papers.

The ecosystem around each framework shapes your daily experience more than the core library. React’s npm registry is vast and chaotic. Vue’s ecosystem is smaller but more curated. Angular’s opinionated approach means fewer choices but more consistency. The framework that lets your team ship features without fighting the toolchain is the right framework, regardless of its technical merits on paper.

The Framework That Ships Wins

Choose the framework your team can debug confidently. Choose the one that fits your hiring pipeline. Choose the one that solves actual problems rather than theoretical ones. The best framework is the one that gets out of your way and lets you build the thing your users actually need.

What framework architecture decisions have shaped your team’s productivity? Have you found that your initial technical choices mattered less than you expected, or have they defined your development experience in ways you didn’t anticipate?